DAXBench: Road to v2
DAXBench v1 was a product of its time. When I released it in December 2025, models were still fairly mediocre at writing DAX.
You could almost watch them translate SQL into DAX in their heads. They made banal syntax errors: a missing argument here, a missing comma there, reserved words used as variable names. Anything involving context transition was a struggle.
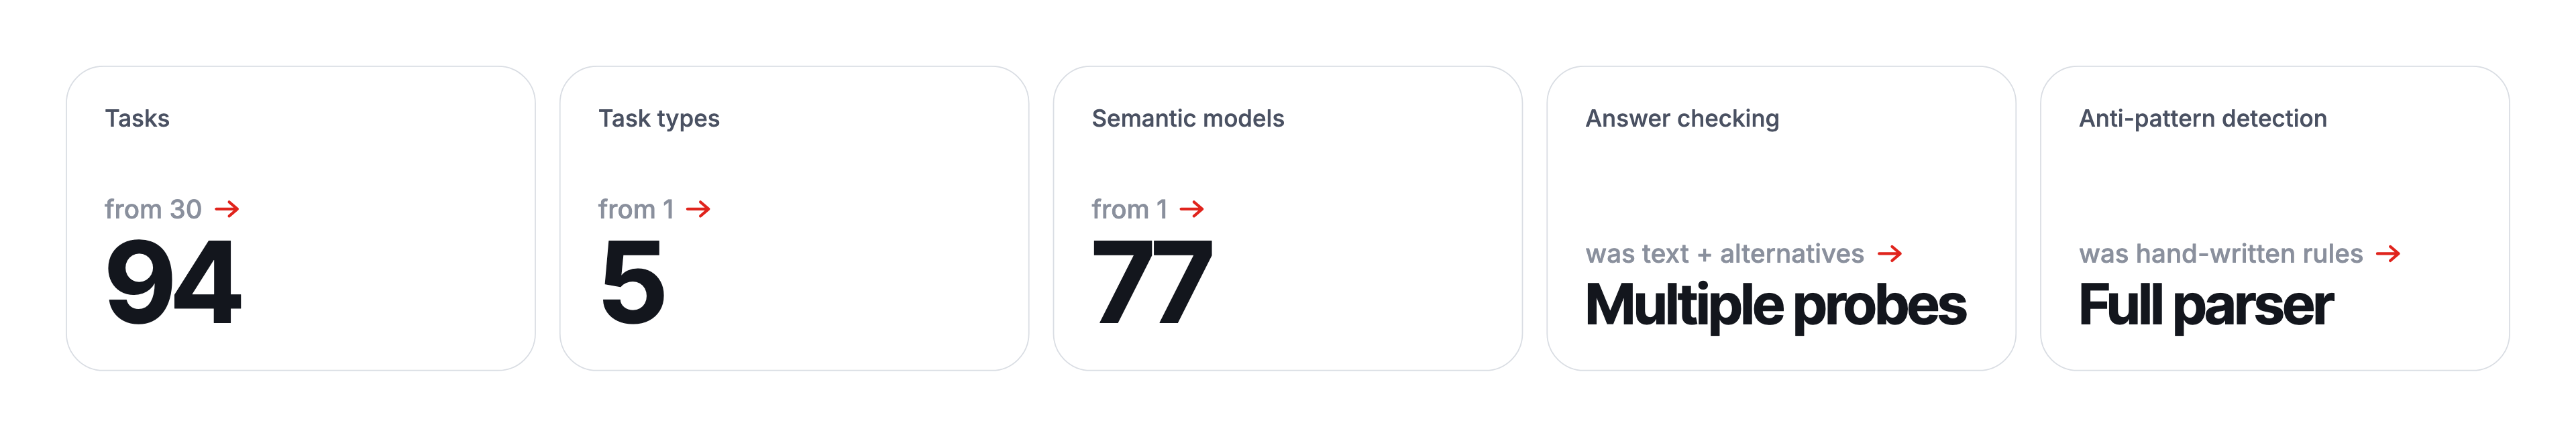
So v1 was limited in scope. I settled on 30 tasks covering the main areas of DAX: aggregation, time intelligence, filtering, calculation, table manipulation, iterators and context transition. The tasks were relatively simple, and simple heuristic scanning for common anti-patterns was enough for the job.
Most frontier models landed around 20 of 30.
That started to change in April 2026, when models, even non-frontier ones, got close to 30/30. There are a few reasons. Some models went through architectural changes that raised their intelligence level. In addition to that every benchmark has to be rotated from time to time anyway. The v1 tasks were never public, but that doesn't fully protect them. Every time you test a model, the prompt goes to the provider, and it may get logged and end up in the training data for the next model versions. V1 had more than 100 models tested, some executed multiple times – that alone eventually would expose tasks to provider logging and as a result becoming part of training dataset.
It was clear it was time for v2: BIGGER, better, with more variety, and with newer features like UDFs that aren't in the training data yet.
What had to change
Looking back at v1, there were few things I wanted to address.
1. The tasks had been seen. Thirty tasks, sent to dozens of models over several months, is a lot of exposure. v2 needed new tasks, more of them, and coverage of parts of DAX that models haven't seen much of yet. That way even if some prompts leak over time, there's far more to memorize, and the newest features aren't in anyone's training data yet.
This is also where v2 stopped being a solo project. I worked on the new tasks with SQLBI, and Marco Russo in particular, who brought in exactly the kind of real-world DAX problems benchmark like this requires: challenges that trip up experienced developers. Marco wrote about v2 from SQLBI's side in the announcement.
2. Sole gold answer isn't sufficient. DAX is flexible. There are many ways to write a measure that returns the same numbers as the gold answer. In v1 I handled this with a gold answer plus a list of alternatives, which meant guessing every valid rewrite in advance. For v2 we wanted some else: any DAX that returns the correct results should be marked as such – correct, whether or not it is written exactly as gold answer.
3. Anti-patterns were defined per task. v1 already penalized bad patterns, but I had to define the anti-patterns for each task by hand. That wasn't always a good fit, again because DAX is so flexible. At the same time, I was building a full DAX parser and scorer for SemanticOps, one that actually understands DAX rather than pattern-matching it. v2 was the obvious place to put it to work.
4. One semantic model doesn't scale. v1 ran everything against a single semantic model. v2 uses 77 of them, each serving one or a few tasks. Nobody deploys and maintains 77 models by hand, so fixture preparation had to be automated as well.
5. More tasks means more ways for us to be wrong. With 94 tasks, some of our own gold answers and checks would be wrong. It was important to separate our own faults in task authoring from the model failures. Therefore every task had to be tested before anything sent to LLMs.
Five rules
Those problems above lay the grounding principles v2 is built around:
- Execution over text. Matching the gold answer's text alone isn't sufficient to pass. All results have to be executed against live model.
- All or nothing. Every check (so-called probe) must pass. There's no partial credit, and no "close enough".
- Executed once. We test raw model capabilities in "one-shotting" correct answer. Obviously, giving model ability to iterate could improve results in some cases, but that moves benchmarking toward testing harness rather than raw intelligence.
- Never blame the model for our failures. A broken gold answer, fixture or Service outage makes a result incomplete and marked as such instead of registering as model failure.
- Frozen and reproducible. Every score traces back to exact inputs and version. Gold answers are never published.
If you're interested in how it all works together, read further down for the technical breakdown.
Let's break v2 down
v2 asks one question: does the DAX return the right numbers in a real model, in every context a report would put it in?
Let's follow how a task moves through v2 pipeline.
Our example (illustrative, not a real benchmark task; those stay private). A measure [Sales % of All Colors] should show each color's share of total sales. The supplied version divides by CALCULATE([Sales Amount], ALL('Product'[Brand])), removing the wrong filter. It looks plausible, and in some visuals it even looks right. Model has to repair the expression.
1. Task definitions
The v2 tasks were developed together with SQLBI. Marco and I went through them for what each one actually tests, where models are likely to go wrong, and whether probes are defined enough to validate correct answer from the wrong ones.
v2 grew three times over, from 30 to 94 tasks, and it tests more than measures now:
| Type | Tasks | What the model gets |
|---|---|---|
| Write measure | 62 | A requirement and the semantic model, write the measure |
| Fix measure (new) | 13 | A measure that returns wrong results, correct it |
| Write UDF (new) | 9 | A required function name and signature, write the function |
| Write calculated column (new) | 7 | A target table, write the column expression |
| Fix & optimize (new) | 3 | A measure that works but is badly written, improve it without changing results |
Fix and fix & optimize sound alike, but they test different things. In a fix task, measure returns wrong numbers. In a fix & optimize task on the other hand the numbers are already correct, problem is in sub-optimal DAX expression. And if LLM returns it unchanged – it would pass every result check, yet still score zero due to the same anti-pattern.
UDFs are the part that was crucial to have in v2. They're new enough that models can't lean on memorized examples.
Our example is a fix task. The supplied measure returns wrong numbers, and LLM has to rewrite measure to produce correct ones.
2. Fixture pipeline
Each task runs against a real semantic model: 77 PBIX files, deployed to the Power BI Service.
The pipeline uploads each one, reads the deployed definition back, and extracts the relevant parts into a pseudo-TMDL description that goes into the task prompt. That way the context the LLM sees is generated from the deployed model, instead of being authored by hand, making sure it doesn't drift from what tasks is supposed to run against. If a column gets renamed, the prompt changes with it.
Our example runs on a small sales model with Sales, Product, Customer and Date. LLM receives prompt that has section dedicated to semantic model: tables, columns, relationships and existing measures, all based on deployed semantic model.
3. Gold gate
Before a task goes into the benchmark, we test the task itself.
- The correct answer must pass. Our own correct answer runs through the same checks the LLMs face. If it fails, the task is broken – it either needs to be fixed, or dropped from the set.
- Known wrong answers must fail. We also run answers we know are wrong: typical mistakes, and in repair tasks the original broken measure. If one of those passes, the checks are too weak to tell right from wrong, and the task needs stronger checks before it can go in.
Task is added into the benchmark only when it's possible to setup probes in a way that consistently validates correct answers and fails incorrect ones. The goal is to be sure that results reflect model capabilities rather than task deficiencies.
And while working on v2 it caught some real problems – as a result one task was retired from v2 entirely because it couldn't be validated properly.
The LLM only ever sees the task and the semantic model. The gold answer, the probes and the known wrong answers never go out in a prompt, so even a logged request doesn't reveal how it's graded.
Our example: the repaired measure passes. The original, which removes the Brand filter instead of the Color filter, must fail. If the checks only looked at the grand total, it would pass, because at the total both versions return 100%.
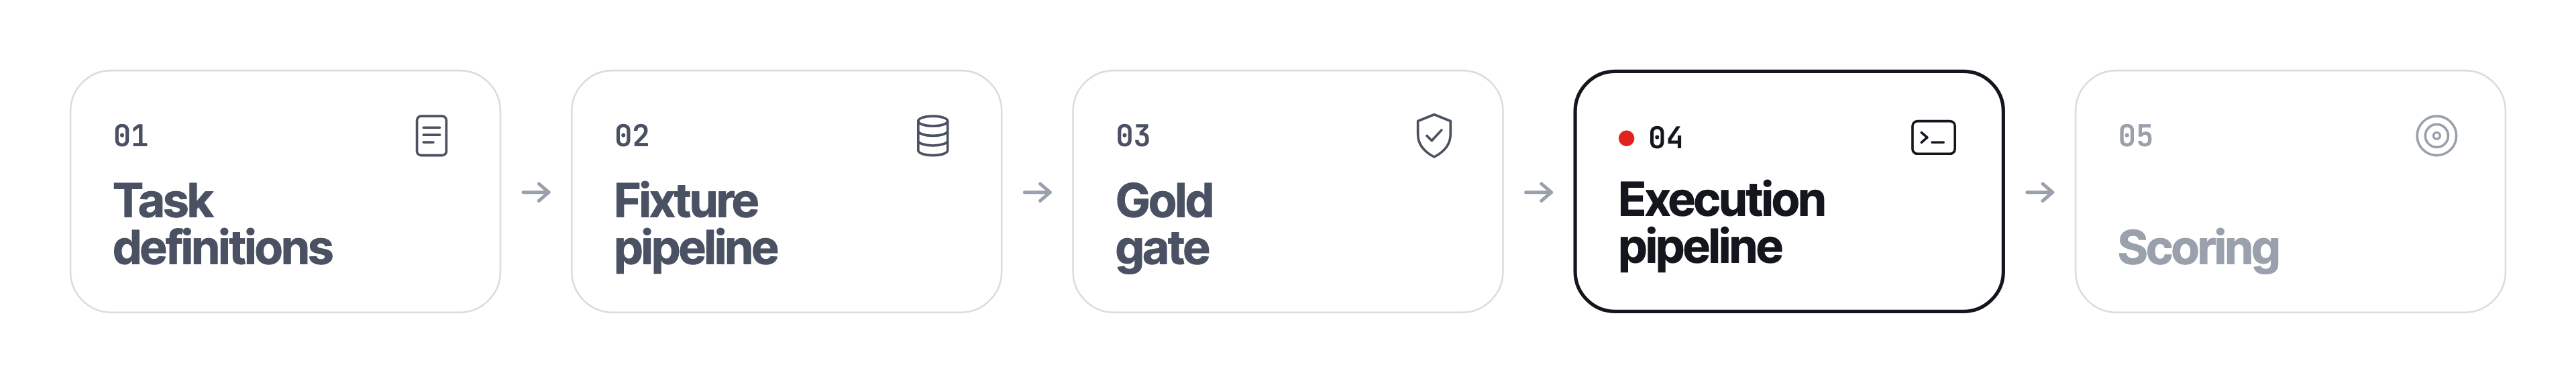
4. Execution pipeline
The LLM's answer (the candidate) is injected into a real DAX query and run in several report-like contexts called probes: detail rows, subtotals, the grand total, slicers, and planted edge cases. Each task has 2 to 6 probes. The gold answer runs through the same probes, and the results are compared within typed tolerances, so currency, ratios and counts each get the right precision.
The candidate only exists inside that query. Nothing is written to the deployed model, and nothing carries over between probes or runs.
Measures are the simple case. The new task types each needed their own handling:
- UDFs. The answer must declare a function with exactly the required name and parameter count, and that's checked before anything runs. Each probe then calls the function its own way. For functions that return tables, we grade which rows come back, not how the columns are named or ordered. A result only counts if it still works as a filter in the model.
- Calculated columns. The column is created inside the query, just for that query. A query-scoped column isn't automatically identical to a real calculated column, so I proved it once: on a disposable copy of each model, the gold answer was added as a real calculated column, and both versions returned the same values. As such confirming the shortcut.
- Fix & optimize. Matching numbers are prerequisite, but in addition to that parser has to confirm the anti-pattern is gone, for example that the measure no longer iterates more rows than it actually needs.
The prompts themselves routed and executed through OpenRouter, which is also source for model identity and pricing.
Our example runs four probes: the grand total, sales by color, sales by brand, and sales by color with a category slicer. A correct repair has to get all four right, not just the one a quick glance would check.
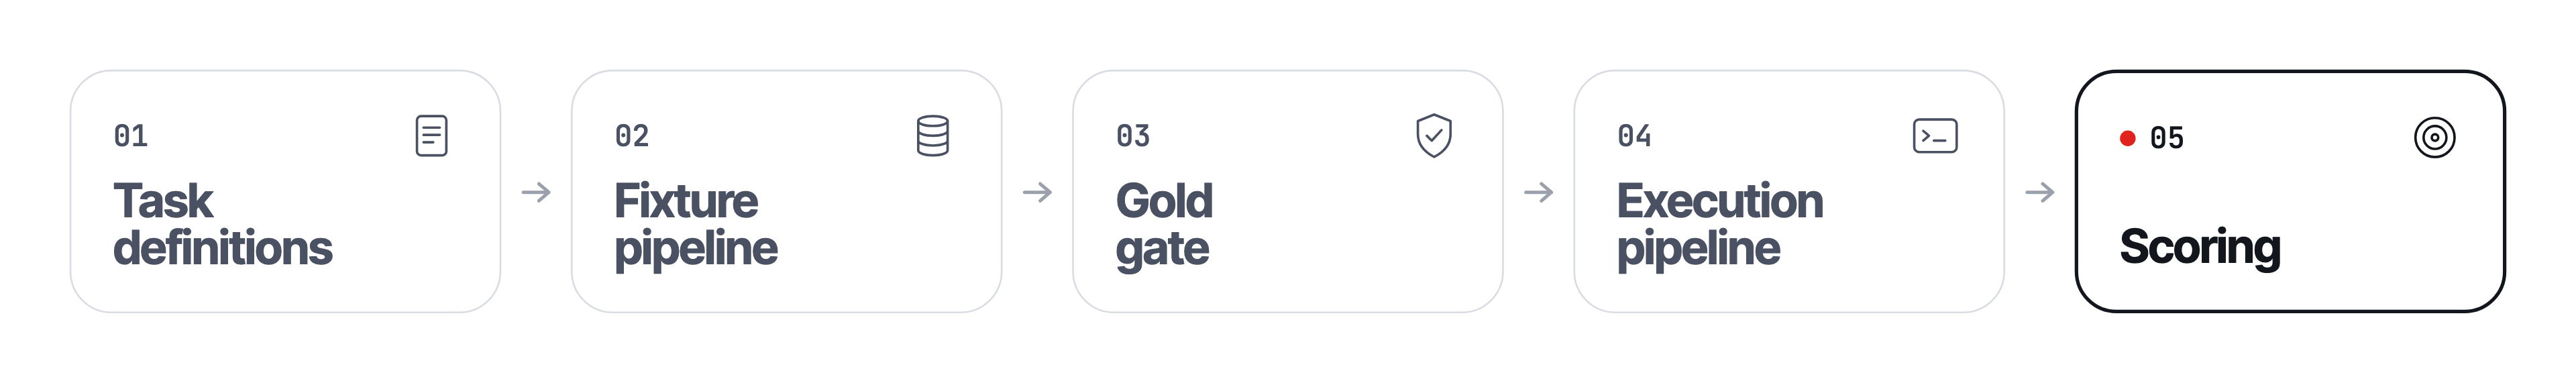
5. Scoring
Marco and I settled on a simple rule: all or nothing. Every probe has to pass for an answer to be correct. Then it gets graded.
Correctness scored first, weighted by complexity. Advanced task is worth more than a basic one. Style (best practices, performance, clarity) is only a bonus, and only for correct answers.
The style and performance grading is where the SemanticOps features I was working on paid off. Instead of my hand-written anti-patterns per task, every answer goes through the full DAX parser and scorer I built to drive SemanticOps. It understands the code structurally, so it judges a rewrite on what the code does in addition to probes validation.
Our example: all probes pass, therefore answer is correct. In addition to correctness points it because code is clearly formatted it earns the style bonus.
6. Reproducibility
Every score is tied to the exact inputs that produced it: the version of the tasks, the deployed semantic models, the parser and scorer version, and the guidance given to the LLM. If any of that change, a run refuses to start rather than quietly producing numbers that can't be compared. Results are stored per model and per reasoning setting, so "the same model, thinking harder" is its own entry rather than overwriting the old one. Albeit in my tests changing reasoning level didn't impact results more than usual variance between runs, LLMs are a slot machine after all.
Review full v2 results here: daxbench.com
DAXBench v2 is developed by Maxim Anatsko in collaboration with SQLBI. Read the SQLBI announcement for Marco's take.